Hosting & SEO
The Website Basics Search Engines Check First: Sitemaps, Canonicals and Structured Data
Sitemaps, canonicals, structured data, and feeds have distinct jobs; verify them against the same public publishing rules.
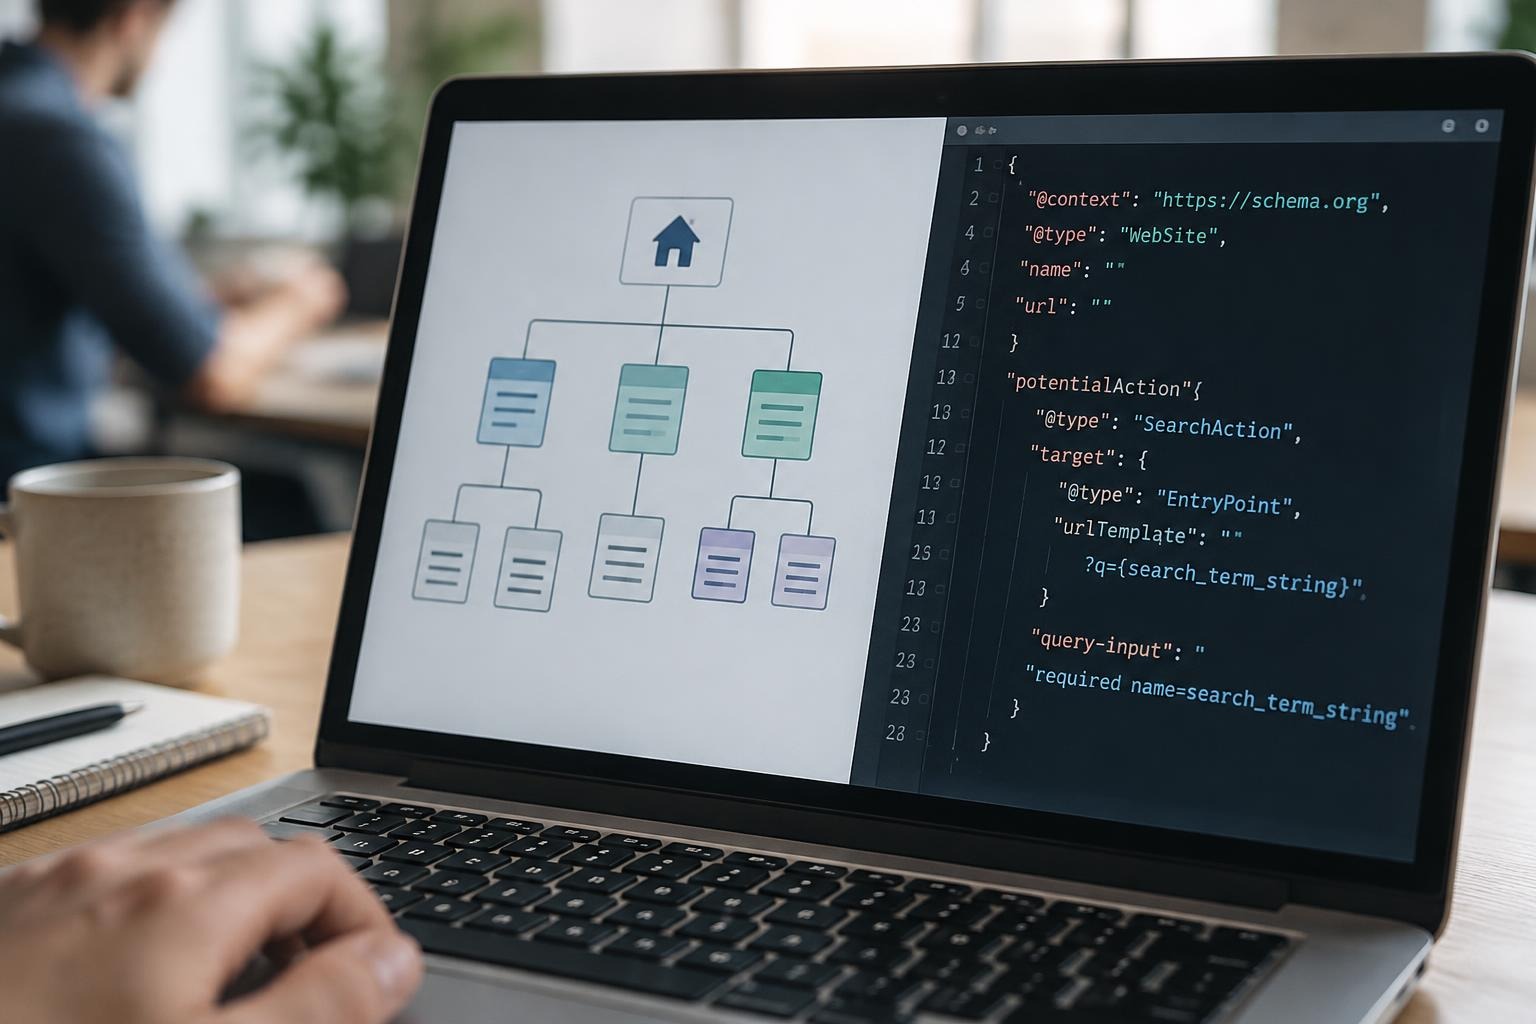
Search engines need a stable address for each page, a route to discover it, and enough structured information to understand what the page represents. We treat sitemaps, canonicals, and structured data as related tools with different jobs, not as interchangeable tags to add at the end of a project.
Give each public page one preferred address
A page may be reached through several URLs: with or without a trailing slash, with tracking parameters, through an alternate hostname, or through a redirect. A canonical link tells crawlers which URL the site considers primary. It does not replace redirects, and it does not force a search engine to accept the choice, but it helps remove ambiguity when pages are otherwise equivalent.
We build canonical URLs from a trusted site origin and the page path, not from an arbitrary host header or a user-supplied parameter. Query strings normally should not become part of a content page’s canonical address. If a route has meaningful variants, decide whether each one deserves to be indexed before emitting a canonical.
Lesko Ballet Academy’s live pages provide a practical example: the blog archive and article pages identify their preferred public URLs, and an article URL remains separate from the archive. A product page, article, and category page should each point to the preferred version that matches its own content. Canonical tags should not all point to the homepage.
Use a sitemap to help discovery
A sitemap is a list of URLs that the site intends search engines to discover. It should include useful public pages, not every file on the server. Keep drafts, private pages, duplicate query variants, redirects, and future-scheduled content out of it. A sitemap is a discovery aid, not an access control mechanism; a page that must remain private needs real authorization.
We generate article entries from the same publication rule used by the public archive: a post must be published and its scheduled time must have arrived. Lesko’s dynamic sitemap lists the public site pages and currently visible articles; future-dated articles stay out until they are due. Using one visibility condition avoids a confusing state where a crawler receives a sitemap URL that the public page itself returns as not found.
Use absolute URLs with the canonical host and a valid XML structure. Add a last-modified value only when it reflects a real content change. Do not update it simply because the sitemap script ran. Then validate the output with an XML parser and compare the URLs against the routes the site actually serves.
Describe the page with structured data
Structured data gives crawlers machine-readable details about an organization or a specific article. It can help clarify identity and relationships, but it does not guarantee a search feature, ranking, or special display. The markup must agree with visible content. If the page does not say that an author wrote an article, do not invent an author in the JSON-LD.
For a business site, Organization data can identify the name, public URL, logo, and contact details. For an article, BlogPosting data can describe the headline, description, image, publication date, author, and canonical URL. BreadcrumbList data can reflect the navigation path a reader sees. Each page should have one coherent graph rather than several conflicting copies generated by different templates.
On Lesko’s live blog, article pages use BlogPosting and BreadcrumbList data alongside the site’s organization information. That makes the markup a useful companion to the visible page, while the canonical URL still establishes the preferred address. We keep dates, headlines, and image URLs consistent across the HTML and JSON-LD.
Pair a blog with a feed
A sitemap and an RSS feed have different readers. The sitemap is primarily for search crawlers; RSS lets feed readers and other subscribers check for new posts. A feed should use valid XML, identify each item with a stable link and title, and describe the publication date accurately. If the archive hides future posts, the feed should use the same rule.
Lesko exposes an RSS feed for the currently published articles. This matters when a publishing system schedules work: a future post should not appear in the feed early, then be removed before the publication date. The archive, article route, feed, related links, and sitemap should agree about visibility.
Keep discovery separate from publication control
Publication state should be enforced at the database query and route layer. A sitemap exclusion alone does not prevent someone from guessing a URL. A feed filter alone does not stop a direct request. We use a shared condition for all public surfaces and return a not-found response for an article that is not yet public.
Before launch, test one due article and one future article. Confirm that the due page appears in the archive, feed, sitemap, and related links. Confirm that the future article appears in none of them and that its direct URL does not render the draft. Move the test date back exactly after the check and query the database to verify it.
Keep crawling rules separate from page visibility
Robots.txt controls crawler access, not whether a person can open a URL. If a page should not appear in search, choose the right indexation rule and make sure a crawler can read it. Blocking the URL in robots.txt can prevent a crawler from seeing a noindex directive. A sitemap also does not make a page private or guarantee that it will be indexed. We treat each control separately: authorization protects private material, publication queries control what the site serves, and crawl directives guide search engines. Test those layers without assuming one file can substitute for the others.
Review the whole chain after a change
- Fetch each canonical URL and confirm it points to the expected public address.
- Parse the sitemap and RSS feed as XML, then check that every listed URL behaves as expected.
- Compare visible article fields with BlogPosting metadata and verify the author and dates.
- Check that the feed, archive, sitemap, related links, and direct route share the publication rule.
- Inspect robots.txt to see whether it names the active sitemap location.
Search visibility starts with accurate routes and consistent publishing rules, not a collection of tags added without testing. We help teams plan this through our SEO service and can discuss a site review through our contact page. For an example of these pieces working together, visit Lesko Ballet Academy. The practical takeaway: verify one page from its HTML through canonical, structured data, sitemap, feed, and direct route before copying the pattern across the site.